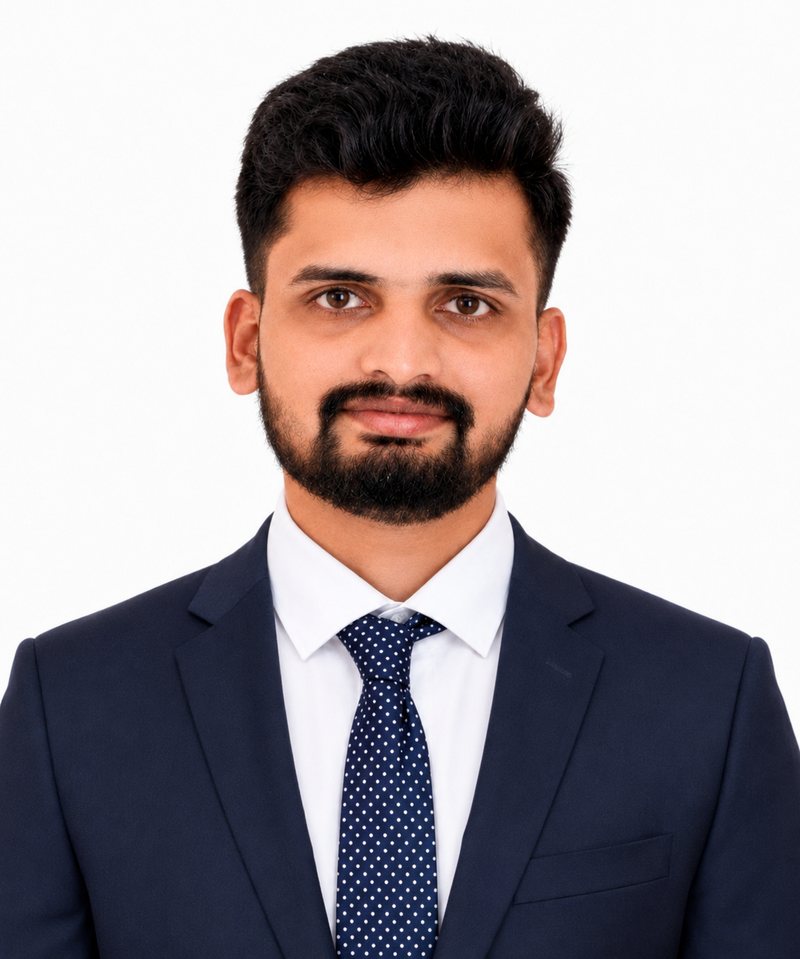
SWAROOP CHAND / AI PLATFORM & AGENT SYSTEMS ENGINEER
Bengaluru, India · Open to global remote
I build the platforms that make enterprise AI reliable.
I’m Swaroop Chand, a machine learning engineer at ResMed with 2+ years of experience. I work on production RAG, agent systems and AI platform engineering, from ingestion and retrieval to agent registries, MCP tools, observability and cloud deployment.
SWAROOP CHAND / AI PLATFORM & AGENT SYSTEMS ENGINEER
Bengaluru, India · Open to global remote
I build the platforms that make enterprise AI reliable.
I’m Swaroop Chand, a machine learning engineer at ResMed with 2+ years of experience. I work on production RAG, agent systems and AI platform engineering, from ingestion and retrieval to agent registries, MCP tools, observability and cloud deployment.
Thirteen case studies across agent systems, retrieval, infrastructure, and applied ML. The contribution, evidence, and limitations travel with each project.
I want to study the systems around intelligent models: how they use evidence, recover from failure, and operate under real constraints.
My starting point is hands-on engineering: enterprise retrieval, agent infrastructure, and applied machine learning for physical systems. I completed an M.Eng. in Artificial Intelligence and Machine Learning at MAHE in 2026, with a CGPA of 9.08.
I am interested in doctoral research and research-engineering collaborations where careful experiments can connect system design decisions to measurable behaviour.
The directions below are proposed investigations, not completed studies or publication claims. My engineering case studies document the work that motivates them.
01
PROPOSED RESEARCH DIRECTION
How should an agent recover from interruption without repeating work or losing the evidence behind its decisions?
This direction connects my previous engineering work to questions that need controlled evaluation, not just an appealing architecture.
Proposed experiment
Compare restart-from-scratch and checkpoint-based recovery on controlled, synthetic tasks with interruptions at defined points.
What I would measure
Task completion, repeated side effects, recovery overhead, and the completeness of the execution trace.
What changes when model inference moves onto the device, but orchestration and tool use remain explicit?
This direction connects my previous engineering work to questions that need controlled evaluation, not just an appealing architecture.
Proposed experiment
Evaluate the independent local assistant under controlled model, memory, and tool configurations. Separate local inference from tools that access a network.
What I would measure
Task success, end-to-end latency, peak memory, and an explicit account of which operations leave the device.
I am Swaroop Chand J C, a machine learning engineer based in Bengaluru, India. I build the systems around AI models: ingestion pipelines, retrieval, connectors, agent runtimes, permissions, observability, and production operations. My aim is to turn fragmented prototypes into enterprise AI capabilities that are secure and ready for production.
At ResMed, I helped evolve a RAG-oriented chatbot framework into a broader AI platform, used to create 150+ assistants. I am now designing how open-source DeepAgents can run inside that platform as a durable agent harness.
I am strongest when a problem crosses boundaries: model behaviour, backend APIs, cloud infrastructure, data quality, and user experience. Before ResMed, at WattWorker, I built models that forecast HVAC power use from building sensor data and predict EV battery life and range. That work keeps my applied ML connected to physical systems as well as software platforms.
I am open to AI platform, agent systems, applied AI, and LLMOps or AI reliability roles, in India or global remote. I am also looking toward international research and research-engineering collaborations where I can build useful systems and investigate why they work.
BENGALURU, INDIA
SWAROOP CHAND ENGINEERING / RESEARCH
PROGRESSION
How my work has progressed.
Each stage reused and extended what the previous stage built. The scope grew from data and retrieval to runtime contracts and governance.
PHASE 01
Knowledge & retrieval foundations. Making enterprise content usable by AI: source connectors, OCR, transcription, embeddings, semantic chunking, and source metadata that keeps answers traceable.
Platformization & lifecycle automation. Turning individual features into shared capabilities: connector registries, workflow-based and parallel processing, unified onboarding APIs, feedback-to-FAQ curation, and production validation.
Agent discovery, runtime execution & governance. Letting users discover agents and invoke them, whether the platform hosts them or they are deployed independently. The focus moved to runtime contracts, endpoint routing, lifecycle, and failure isolation.
Durable agent harness design. Active design work: planning, sub-agent delegation, workspaces, checkpoints, and approval gates on open-source DeepAgents, while keeping the platform’s identity, permissions, secrets, guardrails, and observability.
Associate Machine Learning Engineer · AI Platform & Agent Systems
Agent discovery and registry lifecycle, independently deployed agent runtimes, platform APIs, and AI reliability. Current design work explores durable, governed agent execution.
Jun 2025 - May 2026
ResMed
Data Scientist · Enterprise RAG & Knowledge Platforms
Source-aware ingestion, retrieval controls, enterprise connectors, multimodal knowledge, and human-reviewed feedback workflows for a self-service AI platform.
2023 - 2024
WattWorker Inc.
Machine Learning Research and Developer
Forecasting from building sensor data, physics-informed thermodynamic modelling, and supervised learning for EV battery life and range.
Aug 2022 - Sep 2022
Karunadu Technologies Pvt. Ltd.
Intern · earlier experience
EDUCATION
A foundation to build on.
2026
M.Eng. in Artificial Intelligence & Machine Learning
Manipal School of Information Sciences, MAHE
CGPA 9.08
2023
Bachelor of Engineering
Sapthagiri College of Engineering, Bengaluru
Engineering foundations
HOW I WORK
A few working principles.
01
Know the boundary
Separate model intent from permission, registry metadata from execution, and source knowledge from its search index. Credentials, authorization, and approvals belong in platform controls, not prompt instructions.
02
Make failures inspectable
A useful system explains where it failed. I value explicit contracts, idempotent steps, observable retries, and recovery that can be tested in each environment.
03
Keep claims proportional
Delivered work, prototypes, and proposed designs are different kinds of evidence. The presentation should preserve that distinction and record known limits instead of overstating completion.
RESUME / EXPERIENCE & EDUCATION
The essentials, in one place.
I am an AI platform and agent systems engineer with 2+ years of experience, currently at ResMed in Bengaluru. Start with the summary below; full experience and both PDFs follow.
Case-study links under each role open the full story: the problem, the architecture, the hard part, and the evidence.
May 2026 - Present
ResMed
Associate Machine Learning Engineer · AI Platform & Agent Systems
Agent discovery and registry lifecycle, independently deployed agent runtimes, platform APIs, and AI reliability. Current design work explores durable, governed agent execution.
Agent Hub and registry lifecycle. Implemented an Agent Hub and AWS AgentCore-backed registry lifecycle for registration, discovery, updates, retirement, and endpoint-based execution. Independently deployed agents run through one platform, and built-in execution paths still work.
Web-research agent. Built and deployed a standalone FastAPI/ReAct agent with SSE execution traces, API-key authentication, and web-search and page-reading tools. Diagnosed cluster-egress blocking and added a three-backend fallback that restored grounded, source-cited responses.
Multi-agent SDLC and RCA pilot. Developed a BMAD-based multi-agent pilot spanning planning, development, review, deployment, and incident RCA. It integrates multi-model routing, codebase context, Jira workflows, partial-failure handling, conflict detection, and ranked root-cause hypotheses.
API consolidation. Consolidated approximately 14 onboarding capabilities into a unified FastAPI backend. Validated production workflows across Okta authentication, RAG chat, feedback, notifications, FAQ approvals, access requests, and re-ingestion.
Leak-detection services. Refactored an internal ResNet18 leak-detection application into independent inference and review services with S3-first staging, IRSA, health and metrics endpoints, and failure-safe image retention. Deployed and validated the flow in nonproduction.
Data Scientist · Enterprise RAG & Knowledge Platforms
Source-aware ingestion, retrieval controls, enterprise connectors, multimodal knowledge, and human-reviewed feedback workflows for a self-service AI platform.
Self-service RAG platform. Built and hardened core components of a self-service enterprise RAG platform used to create 150+ assistants, including 2 customer-facing deployments and 10+ active internal bots. End-user chatbot deployment time fell from weeks to minutes.
Faster onboarding. Reduced document-onboarding time by 31–40% in measured PDF workloads through bounded parallel processing and embedding-pipeline optimization. Measured runs: 5 documents from 10 to 6 minutes, 40 documents from 118 to 81 minutes.
Connectors and freshness. Expanded coverage across Confluence, SharePoint, GitHub, Workday, PDFs, tables, images, and videos. Built an OAuth2 Workday connector for approximately 1,145 help articles with incremental sync, and added SHA-256 change detection and stale-record deletion.
Human-reviewed FAQ workflow. Delivered a human-in-the-loop FAQ correction workflow with bot-owner approvals, idempotent queueing, S3 persistence, automatic re-embedding, OpenSearch updates, and owner notifications, then hardened it in nonproduction.
Forecasting from building sensor data, physics-informed thermodynamic modelling, and supervised learning for EV battery life and range.
HVAC forecasting. Developed RNN, CNN, XGBoost, Random Forest, and H2O AutoML models for HVAC power-consumption forecasting, using noisy sensor data from 3 commercial buildings in the UK and US. Reported model performance improved from 78% to 94% through hyperparameter optimization.
Physics-informed models. Built thermodynamic models from physical equations and curve fitting to estimate indoor-temperature dynamics, and presented control and operational insights to stakeholders.
EV telemetry. Developed supervised-learning models for EV battery remaining useful life and range prediction, and analyzed GPS telemetry for route, trip, and operational patterns.
Hybrid search (dense/sparse, BM25), cross-encoder reranking and RRF, semantic chunking, metadata filters, per-source Top K, multilingual retrieval, OpenSearch, pgvector, and vector databases.
Knowledge ingestion & integration
Multimodal ingestion of PDF, DOCX, PPTX, XLSX, CSV, JSON, Markdown, and YAML; OCR, transcription, and image/video processing; GitHub, Confluence, SharePoint, and Workday sources; Jira and Snowflake MCP; Kafka.
Backend & cloud
Python, FastAPI, Flask, Pydantic, REST and streaming APIs, microservices, PostgreSQL, Redis, AWS Bedrock, S3, RDS, Secrets Manager, IRSA, and OIDC/JWKS.
Deployment, LLMOps & observability
Docker, Kubernetes, TrueFoundry, GitHub Actions, multi-environment promotion, OpenTelemetry, Datadog, AI traces, AI evaluation, and multi-hypothesis RCA.
Machine learning
PyTorch, TensorFlow, Transformers, CNNs, RNNs, ResNet18, XGBoost, Random Forest, H2O AutoML, scikit-learn, Pandas, NumPy, and model serving through inference APIs.
CONTACT / START A CONVERSATION
Good work starts with a conversation.
I am an AI platform and agent systems engineer at ResMed in Bengaluru, open to global remote roles. Hiring for AI platform or agent systems work, or researching agent recovery, retrieval evidence, or on-device agents? Email is the most direct way to reach me.
This static website does not include analytics, advertising, a remote font service, a contact-form processor, or an AI backend. Search and the runtime simulation run in your browser. Search queries are not sent to a server by the application.
Local preferences
The light/dark theme choice is stored in your browser's local storage when available. The runtime simulation is kept only in memory and discarded when you reset or leave its page.
External links and hosting
Email links open your own email application. GitHub and LinkedIn links take you to those services. Their policies apply on those sites. The chosen hosting provider may process ordinary connection metadata, such as IP addresses and requested pages, under its own policies.
Portfolio content
Industry case studies are generalized summaries. They do not include employer source code, customer data, internal links, private hostnames, or secret identifiers. Claims of delivery, prototypes, and active architecture are intentionally distinguished.
404 / THAT ROUTE ENDS HERE
Let’s take another path.
The page you are looking for is not here. The selected work is a good place to start.
Agent Hub is where people find and launch agents, whether the platform hosts them or a team deploys them as a separate service. I implemented the hub, its endpoint-backed execution path, a standalone research agent and the governed registry lifecycle behind it.
The problem
Teams needed one place to discover agents, manage ownership and run them. Some specialist agents run as separate services, and a catalogue alone cannot invoke, update or retire them.
What I did
Built Agent Hub and an endpoint-backed execution path. Built and deployed a FastAPI/ReAct web-research agent. Implemented AWS AgentCore-backed register, discover, update and retire flows, routed by environment and registration source.
Result
Independently deployed agents now run through the same hub as built-in ones, and existing agents kept their execution path. A three-backend fallback restored grounded, source-cited answers from the deployed research agent.
SYSTEM AT A GLANCECONCEPTUAL VIEW / NOT INTERNAL TOPOLOGY
01Register agent
02Discover in Agent Hub
03Resolve route
04Invoke endpoint or built-in loop
05Stream traced result
The registry holds governed metadata and routing. The agent itself can run as a separately deployed service.
3 backendsin the web-search fallback chain; diagnostics, not a guess, if all fail
2 execution pathsbuilt-in loop or proxied endpoint, behind one hub
4 lifecycle flowsregister, discover, update and retire, on registries separated by environment and source
The problem
The platform began as a RAG chatbot framework. The first version of Agent Hub was a searchable catalogue of agents with metadata, ownership and launch behaviour.
That was not enough. Teams needed one place to discover agents, manage ownership and run both platform-hosted agents and agents deployed as separate services. A catalogue can describe an agent. It cannot invoke a remote service, apply a changed endpoint or retire an obsolete one.
Do not break existing agents. Agents on the built-in execution loop had to keep working without a migration.
Do not dictate the runtime. Teams should keep the framework and hosting model that fits their use case.
Keep registrations clean. Platform-created and user-registered agents needed separate registries in each environment, and a bad registration could not leave an inconsistent entry.
How it works
The design separates two questions: which agents exist, and where each one runs.
Registry record. Each agent is registered with a name, description, skills, framework or runtime, endpoint, category, owner, access and lifecycle metadata.
Agent Hub. People search and filter the registry to find an agent and launch it.
Routing. If a record has an endpoint, the hub proxies execution to that service. If it has none, the existing built-in loop runs the agent.
Separate registries. Lookups resolve deterministically by environment and by registration source.
Lifecycle. Changes to metadata or endpoints apply to later runs. Retired agents drop out of normal discovery and invocation.
The independently deployed agent in this work was a web-research agent: a standalone FastAPI service running a ReAct loop with web-search and page-reading tools. It authenticates callers with an API key and streams its execution trace over Server-Sent Events.
What I built
Agent Hub. I implemented the hub for discovery and launch, then extended it so a record with an endpoint proxies execution to an independently deployed service.
Backward-compatible routing. Entries without endpoints kept the built-in execution loop, so no existing agent had to change.
A standalone research agent. I built and deployed the FastAPI/ReAct web-research agent with SSE traces, API-key authentication, web search and page reading.
Registry lifecycle. I implemented AWS AgentCore-backed flows to register, discover, update and retire agents. Duplicate or incomplete registrations fail cleanly.
Environment and source separation. I added deterministic routing so platform-created and user-registered agents land in separate registries for each environment.
Exploration before build. Before the lifecycle work, I explored AgentCore Registry for registration, discovery, metadata and endpoint-backed execution.
The work was delivered in phases. Agent Hub and registry discovery came between May and July 2026. The governed registry lifecycle followed in August and September 2026. Governance hardening continues.
Decisions that mattered
Keep metadata and workloads apart
The registry stores governed metadata and routing information. It does not host the agent. Teams keep their runtime choice, and the platform still owns discovery, ownership and lifecycle.
Make the endpoint optional
An endpoint switches a record to proxied execution; no endpoint means the built-in loop. That one rule added a new execution model without forcing existing agents to migrate.
Route deterministically
Separate registries by environment and registration source mean every lookup resolves to one known registry.
Fail cleanly on bad registrations
A duplicate or incomplete registration fails without leaving an inconsistent entry for discovery to find later.
Return evidence, not a guess
When every search backend fails, the research tool returns diagnostics. The agent can rephrase or read a page directly instead of fabricating an answer.
The hard part
Symptom. The research agent’s web search worked locally. In the cluster, the same call returned an empty HTTP 202 response, so the agent had nothing to read.
Diagnosis. An empty result like this is easy to misread as a model failure. Instead, I reproduced the behaviour at the network boundary. The upstream HTML search endpoint was blocking datacenter egress IPs. The fault was in the environment, not the agent’s reasoning.
Fix. I replaced the single search call with a three-stage fallback chain across three search backends. If all of them fail, the tool returns diagnostics rather than an empty success, so the agent can rephrase or read a page directly.
Verified. The deployed agent recovered, fetched pages and produced source-cited answers.
The lesson I kept: an empty upstream response should never quietly become an answer.
Evidence & outcome
The delivery record documents the registry launch, endpoint routing, streaming tool traces and source-cited output from the deployed research agent. Registry lifecycle work landed in successive phases, and some phases have less complete automated-test and deployment evidence than others.
For users: one place to discover and invoke agents, whether or not the platform hosts them.
For agent teams: freedom to deploy a specialist runtime with the framework and hosting that fits.
For the platform: discovery, ownership and lifecycle stay central and governed.
For answer quality: search failures surface as diagnostics, which lowers the risk of a fabricated answer.
The outcome
A reusable pattern for governed agent discovery and execution that does not force every agent into one runtime or hosting model.
Connecting agents to enterprise systems
In October 2026 I worked on integrations for an enterprise assistant that needed reliable access to event-driven business processes and governed analytical data. My role was integration design and support. The core integration is delivered, and refinement continues.
Governed analytical data. Snowflake access sits behind an MCP boundary, so the assistant uses governed data operations without database-specific logic in the conversational runtime.
The design follows the same platform pattern as Agent Hub: the platform discovers and permissions tools, and each data system stays behind a dedicated integration contract. Failure handling and environment configuration were part of the integration design, not afterthoughts.
Team platform work. This is a generalized account of my part of a shared platform, not a claim of sole ownership.
Governance hardening continues. Private endpoint authentication, health and version checks, audit events and the retirement flow need stronger recorded evidence.
No adoption numbers yet. Next I would measure registered agents, lifecycle operations, and endpoint success rate and latency.
Integration evidence. End-to-end payload and query traces, operational ownership and failure-path validation are still to be captured.
Based on my documented work record, reviewed October 2026. Industry details are generalized: internal product names, employer code, customer identities, private links and infrastructure identifiers are not reproduced, and private integration chains are described generically. This account is not an independently audited benchmark.
Structure-aware ingestion and 31–40% faster PDF onboarding.
A source-aware ingestion and embeddings pipeline that makes tables, JSON, Markdown, PDFs, YAML, images and video searchable and reusable across bots and agents. I built the format-specific processing, modernized the embeddings workflow and parallelized document processing.
The problem
A generic text pipeline could not keep the structure of tables, JSON, YAML, scanned PDFs or video, or the source context answers need. Embeddings ran as one monolithic job that processed large document sets in sequence.
What I did
Built source-aware extraction and chunking for each format. Moved the embeddings job into explicit workflow stages, added bounded parallel processing and hardened OpenSearch indexing for long bulk uploads.
Result
Recorded onboarding runs fell from 10 to 6 min for 5 PDFs and from 118 to 81 min for 40 PDFs. Index creation now fails fast with the real OpenSearch error instead of swallowing it.
SYSTEM AT A GLANCECONCEPTUAL VIEW / NOT INTERNAL TOPOLOGY
01Configure
02Fetch
03Extract by format
04Chunk by structure
05Embed
06Store & index
Source-aware at extraction and chunking; one indexing and retrieval contract downstream. Each stage can be retried, parallelized and reported on separately.
118 → 81 minrecorded 40-PDF onboarding run, about 31% faster
150+assistants created on the wider platform this pipeline serves
The problem
Enterprise knowledge does not arrive as clean prose. It comes as spreadsheets, JSON exports, Markdown, scanned PDFs, YAML and templates, images and video. Each source also brings its own credentials, deletion rules, scale and metadata.
A generic text pipeline could not handle that variety. Flattening a table or a YAML file into plain text loses the headers, keys and indentation that make a chunk meaningful. Losing the source URL makes an answer hard to trace.
The embeddings process was also one monolithic job. Large document sets ran in sequence, with no stage boundaries for retries, parallel execution or stage-level failure reporting.
One contract downstream. Each source could be processed differently, but all of it had to land in one consistent indexing and retrieval contract.
Long-running jobs. Bulk uploads could outlast their AWS credentials, and index settings had to suit each environment’s cluster.
Traceable answers. Source metadata and URLs had to survive every stage.
How it works
Processing is source-aware at the edges and uniform in the middle. Each format gets its own extraction and chunking. After that, everything follows one path into storage and the search index.
CSV and Excel. Rows become header-aware natural-language text, with deterministic tabular pre-chunking instead of prose-oriented semantic splitting.
JSON. Objects and arrays are flattened recursively into readable key paths, keeping logical object boundaries.
Markdown. Split by heading hierarchy, with source URLs kept for traceable retrieval.
PDF. Native extraction combined with layout-aware OCR for scanned or complex documents.
YAML and templates. Indentation and case are preserved. Multi-document YAML is split by structure, and templates by named blocks or directives.
Images. OCR text plus visual descriptions suitable for semantic search.
Video. Speech transcription combined with sampled-frame analysis, keeping time and source metadata.
The embeddings workflow runs as explicit stages: configuration, fetch, extraction, chunking, embeddings, storage and indexing. Each stage has its own retries, metrics and failure reporting.
Connectors for GitHub, Confluence, Workday, SharePoint and S3 feed this pipeline, and retrieval controls sit on top of the index. Connectors, retrieval and the image and video workstream each have their own case study.
Format-specific processing. I built source-aware extraction and chunking for CSV and Excel, JSON, Markdown, PDF, YAML and templates, images and video, instead of one generic text pipeline.
Traceable metadata. I designed source-aware metadata and URL preservation so answers stay traceable to their origin.
Staged embeddings workflow. I migrated the embeddings process from a monolithic job into explicit workflow stages.
Parallel document processing. I added bounded parallel processing, with stage metrics and failure notification so speed did not cost visibility.
OpenSearch reliability. For long bulk uploads I added proactive credential refresh and expired-token retry. I made shard and replica counts environment-configurable, and index creation fail fast and idempotent under concurrency.
One failure path. I centralized failure notification so an error in any workflow stage reaches the user.
Parser and OCR evaluation. I evaluated Apache Tika and PDF-conversion alternatives for complex office documents and PDFs, and recorded where OCR or native extraction fit better. I then integrated OCR for scanned documents.
The foundations, including PDF and OCR evaluation, came in mid to late 2025. Parallel processing, the workflow migration and OCR productionization followed in early 2026.
Decisions that mattered
Preserve the source’s structure
Tables become header-aware rows with deterministic pre-chunking, not prose splits. JSON keeps its key paths and YAML keeps its indentation. One chunking strategy cannot serve prose, tables, YAML, templates and JSON equally well.
Vary the edges, keep one contract
Format-specific logic lives in extraction and chunking. Storage, indexing and retrieval stay the same for every source, so a new format plugs into the same downstream path.
Make stages explicit before going parallel
Splitting the monolithic job into stages is what made parallel execution, retries, failure reporting and stage-level metrics possible. Parallelism arrived with that visibility, not instead of it.
Fail fast with the real error
Index creation fails with the real root cause instead of swallowing it, and concurrent creation of the same index is idempotent. Every stage reports failures through one path.
Size the index per environment
Shard and replica counts come from environment configuration, which avoids unnecessary pressure on the cluster.
The hard part
Symptom. Document onboarding was too slow. Large document sets ran one after another inside a monolithic job; a recorded 40-PDF run took 118 minutes.
Diagnosis. Documents were handled strictly in sequence, and the monolithic job had no stage boundaries to parallelize around. Any speed-up also had to keep failure isolation and observability.
Fix. I migrated processing into workflow stages, parallelized document handling with a bound on concurrency, and added stage metrics and failure notification.
Verified. The recorded 5-PDF run fell from 10 to 6 minutes (40% faster). The 40-PDF run fell from 118 to 81 minutes (about 31% faster).
What parallelism did not fix. Faster workers can still hold too much data. In later customer-owned S3 testing, memory rose by roughly 20 GB when about 10,000 objects were accumulated in a list. The documented follow-up is for connectors to stream documents and release each one after processing.
The lesson I kept: parallelism is not a memory strategy.
The speed-ups come from two recorded PDF workloads, measured before and after parallelization. They describe those workloads, not a guaranteed speed-up for every format or document size.
Coverage. Files, repositories, enterprise applications, images and video go through one reusable ingestion path.
Onboarding time. 10 to 6 minutes for 5 PDFs; 118 to 81 minutes for 40 PDFs.
Failure diagnosis. Centralized failure notification and real OpenSearch errors made failed onboarding jobs easier to diagnose.
Platform reach. The pipeline feeds a platform used to create 150+ assistants, including 10+ active enterprise bots and 2 customer-facing deployments.
The outcome
Reusable, source-aware ingestion across many content types, with lower elapsed onboarding time in the recorded PDF workloads and failures that report their real cause.
Limits & next steps
Two workloads, not a benchmark. The speed-ups are for two recorded PDF runs. I do not claim the same gain for other formats or sizes.
Memory is the next scale limit. Streaming fetch is the documented follow-up, not a delivered result. The metrics to capture are peak memory, throughput and completion time after streaming.
Answer quality is measured separately. This page covers getting content in. Retrieval quality has no published golden-set benchmark yet; the retrieval case study covers that work.
Shared platform. The adoption figures describe the platform I contributed to, not 150 individually hand-built assistants.
Based on my documented work record, reviewed October 2026. Industry details are generalized: internal product names, employer code, customer identities, private links and infrastructure identifiers are not reproduced. The timings are recorded workloads, not an independently audited benchmark.
Ingesting customer-owned S3 directly, without copying data.
A connector that onboards documents straight from a customer’s own AWS bucket, so nothing has to be copied into a platform bucket first. I built the backend connector, its credential isolation and its object-key handling, and validated it end to end.
The problem
Customers who already kept documents in their own S3 buckets had to copy them into the platform’s bucket before onboarding. That duplicated data, added manual work and was impractical at tens of thousands of objects.
What I did
Built the connector: connection test, object listing, bot-scoped credentials that the workflow resolves at fetch time, and workflow integration. Replaced a URL parser that cut keys at the # character with a byte-preserving key splitter.
Result
Listed 59,202 objects from a representative customer bucket, and the workflow populated OpenSearch. The job configuration holds object URIs, never credentials, and missing credentials fail explicitly.
Stack
PythonFastAPIboto3AWS S3Secrets ManagerOpenSearch
SYSTEM AT A GLANCECONCEPTUAL VIEW / NOT INTERNAL TOPOLOGY
01Test access
02List objects
03Record URIs
04Resolve secret at fetch
05Extract & embed
06Index
The job configuration carries object URIs, never keys. Credentials live in a bot-scoped secret, and the workflow resolves them when it fetches content.
59,202objects listed from a representative customer bucket in end-to-end validation
~20 GBmemory rise at about 10,000 accumulated objects, which set the streaming follow-up
The problem
Some customers already kept their document collections in their own AWS S3 buckets. To onboard them, the documents first had to be copied into the platform’s internal bucket.
That copy duplicated content and added operational work to every onboarding. For collections of tens of thousands of objects, it was impractical.
Customer keys, isolated. The connector reads with credentials the customer provides. One customer’s keys had to be rotatable or removable without touching a shared secret.
No silent identity fallback. If customer credentials are missing, the connector must not quietly read with the platform’s own pod identity (IRSA).
Real object names. S3 keys can contain characters such as #, ?, % and spaces, which mean something else inside a URL.
Scale. A single source can hold tens of thousands of objects.
How it works
The connector adds customer-owned buckets as a source in front of the existing ingestion pipeline. Everything after fetch reuses the standard stages.
Configure. The source names the customer bucket, its region, an optional prefix and the customer’s credentials.
Test the connection. Access is checked with the customer’s own credentials.
List objects. The connector lists the bucket, scoped by region and the optional prefix.
Record references. Source URIs go into the job configuration. The credentials go into a secret scoped to that bot.
Fetch at run time. The workflow resolves the credentials from the secret when it fetches objects. If they are missing, it fails with an explicit error.
Process. Fetched objects go through the standard extraction, chunking, embeddings and OpenSearch indexing stages.
My scope was the backend connector, credential isolation, URI correctness, workflow integration and end-to-end validation.
Connection test and listing. A connection test that uses the customer’s credentials, and object listing with region and optional prefix.
Bot-scoped credential storage. Both required credential values go into a per-bot secret. The job configuration receives only source URIs.
Fetch-time resolution with an explicit failure. The workflow resolves credentials when it fetches. Missing credentials raise an error; there is no fallback to the pod identity.
Byte-preserving URI handling. A manual s3://bucket/key splitter that keeps #, spaces, ?, %, &, non-ASCII characters and the exact byte sequence of each key.
Workflow integration. I connected the new source to the existing ingestion workflow, so fetched objects reuse the standard processing stages.
Automated tests. Coverage for the constructor, credential handling, registry dispatch, partial failures and parser edge cases.
The work landed in August to September 2026, alongside cross-account onboarding.
Decisions that mattered
Keep references and credentials apart
The job configuration carries object URIs. The keys stay in a secret and are resolved at fetch time, so credentials never travel with the job definition.
One secret per bot, not a shared one
Each customer’s keys sit in a secret scoped to that bot. They can be rotated or removed without changing a shared secret.
Fail loudly when credentials are missing
Missing credentials are a configuration error, so the connector reports one. It never quietly reads with the platform’s own pod identity instead.
Treat object keys as bytes, not URLs
An S3 key is not a URL. Splitting s3://bucket/key by hand keeps characters that a URL parser would read as a fragment, a query or an escape.
Validate each stage on its own
I checked connection, listing, job configuration, secret contents, workflow acceptance and indexing separately. Because listing passed while fetch failed, the fault was narrowed to how keys reached the SDK.
The hard part
Symptom. The first end-to-end run listed the bucket successfully. Fetching then failed with NoSuchKey for objects whose keys contained #.
Diagnosis. I owned the end-to-end diagnosis. Listing showed the objects existed, so the key was changing on its way to the SDK. A standard URL parser treats # as the start of a fragment. It cut the key at that character, and the SDK asked for an object that does not exist. In an illustrative case, a key like report#final.pdf would arrive as report.
Fix. I replaced the generic URL parsing with a manual s3://bucket/key splitter. It preserves #, spaces, ?, %, &, non-ASCII characters and the exact byte sequence of the key. I added parser edge-case tests.
Verified. I reran the workflow. The connector processed the source and populated OpenSearch.
What the rerun exposed next. Once keys survived, a separate limit appeared. Memory rose by roughly 20 GB when about 10,000 objects accumulated in a list. That finding set the streaming/generator follow-up.
The lesson I kept: an object key is data to preserve, not a URL to parse.
Evidence & outcome
Validation ran against a representative customer bucket. The record documents each check:
Listing. 59,202 objects listed.
Job configuration. The trigger produced a job configuration with source URIs and no raw credentials.
Secret. Both required credential values were stored in the bot’s secret.
Workflow. The workflow accepted the source and populated OpenSearch.
Tests. Automated tests cover the constructor, credentials, registry dispatch, partial failures and parser edge cases: 14 unit tests and 7 URI parser cases.
Customers can now onboard from storage they control, without the manual copy into a platform bucket.
The outcome
Direct onboarding from customer-controlled S3, with per-bot credential isolation, no silent identity fallback and object keys that survive real filenames. Validation also surfaced the next scale requirement: streaming fetch instead of in-memory accumulation.
Limits & next steps
Listed is not embedded. 59,202 is the number of objects listed. It is not a claim that every listed object was extracted and embedded.
Memory is the open limit. Accumulating objects in a list caused a roughly 20 GB memory rise at about 10,000 objects. A streaming/generator fetch is follow-up work, not a delivered result.
What I would measure next. Throughput, peak memory and completion time after streaming, plus server-side filtering benchmarks.
Generalized security model. This account describes the credential model without bucket names, secret names, account identifiers or authorization topology.
Based on my documented work record, reviewed October 2026. Industry details are generalized: the customer, bucket and secret names, account identifiers, employer code and internal infrastructure are not reproduced. The object count is a validation listing, not an independently audited benchmark.
A fully local assistant with nine specialized agents.
An independent project: a ReAct-based assistant whose nine specialized agents are orchestrated through LangGraph. Model inference runs on the device through Apple MLX, with no cloud dependency, and tools connect through MCP.
The problem
I wanted an assistant whose model inference stays on the device, so private requests do not depend on a cloud model service. It still had to coordinate specialized agents and tools.
What I did
Built a ReAct-based assistant with 9 specialized agents orchestrated through LangGraph. Integrated Apple MLX for on-device inference and MCP for tool access.
Result
A working, fully local assistant: 9 specialized agents and MCP tools on private on-device MLX inference, with no cloud model dependency.
Stack
PythonApple MLXLangGraphMCPReAct
SYSTEM AT A GLANCECONCEPTUAL VIEW / NOT A BENCHMARKED CONFIGURATION
01Local request
02LangGraph orchestration
03Specialist agent
04Reasons with MLX on-device
05Acts through MCP tools
Each agent reasons with a local model and acts through MCP tools. Model inference stays on the device.
The problem
I wanted to explore an assistant whose model inference runs on the device rather than depending on a cloud inference service.
The goal was private, on-device inference without giving up the structure of a multi-agent system.
Inference on the device. No hosted model endpoint in the loop.
Specialization. Separate agents for separate jobs, with explicit coordination between them.
Tools through one interface. Tool access through a standard protocol rather than operations hard-wired into the model interaction.
How it works
Orchestration. LangGraph coordinates nine specialized agents as an explicit graph.
Reasoning loop. The assistant follows the ReAct pattern: reason about the next step, act through a tool, observe the result, and repeat until it can answer.
Local inference. Apple MLX runs the model on the device.
Tools. Tools connect through MCP instead of being hard-wired into the model interaction.
What I built
I built the assistant end to end as an independent project.
The agent system. A fully local, ReAct-based assistant with nine specialized agents orchestrated through LangGraph.
On-device inference. I integrated Apple MLX, so the model runs locally.
Tool integration. I connected the agents to tools through MCP.
Decisions that mattered
Keep model inference local
Use the device as the inference boundary rather than defaulting to a hosted model endpoint.
Make specialization explicit
Use a graph-based orchestration layer to coordinate the specialized agents, so the control flow between them is visible.
Keep tools behind an interface
Integrate tools through MCP instead of hard-wiring every operation into the model interaction.
The hard part
The hard boundary is between local inference and tool use.
Running the model on the device keeps prompts and generated text local. Tools are a separate boundary: an MCP tool that calls a network service would send data off the device, even with a local model.
So “fully local” is a property of the whole system, the model and every connected tool. A local model does not by itself prove that every tool is offline or that no data leaves the device.
So I state the claim at the level I can support: the model and orchestration run on the device, with no cloud inference dependency. A tool-by-tool account of what each tool can reach is the next thing I would document.
Evidence & outcome
What I can show is the built system and its architecture, not benchmark numbers. It is a fully local ReAct-based assistant with nine specialized agents orchestrated through LangGraph, Apple MLX inference and MCP tools.
The outcome
A working, fully local multi-agent assistant, and a concrete starting point for my research questions on on-device agent systems.
No benchmarks yet. No latency, task-success, quality or memory figures are claimed here.
No published configuration. This account does not list agent roles, model choices or tool configuration, and no repository or reproducible benchmark is published with it.
No tool-network audit. This account does not include a tool-by-tool audit of network access.
What I would measure next. Run the assistant under controlled model, memory and tool configurations, with local inference separated from tools that reach a network. Measure task success, end-to-end latency, peak memory, and exactly which operations leave the device.
Independent project, described from my resume, reviewed October 2026. No benchmark results are claimed, and agent roles, model choices and tool configurations are not listed. This account is not an independently audited benchmark.
Turning user corrections into owner-approved FAQ answers.
A workflow that captures disliked answers and user corrections, routes them to the bot’s owner, and turns the approved ones into re-indexed FAQ knowledge. I built the queue, approvals, notifications, source updates and re-embedding, then hardened the flow across dev and nonprod.
The problem
Users could dislike an answer and supply a correction, but nothing turned a good correction into reusable knowledge. Writing feedback straight into retrieval would bypass the bot owner, the FAQ source file and re-indexing.
What I did
Built a pending queue for disliked answers and corrections, owner notifications with pending counts, and individual or bulk approve/reject. Approval updates the bot’s FAQ source file in S3, triggers re-embedding and updates its OpenSearch FAQ index.
Result
Approving a correction now updates the bot’s FAQ file in S3 and its OpenSearch FAQ index with no manual step; unreviewed feedback never reaches retrieval. Stable in nonprod after five environment-parity fixes.
SYSTEM AT A GLANCECONCEPTUAL VIEW / NOT INTERNAL TOPOLOGY
01Capture feedback
02Notify owner
03Approve or reject
04Update FAQ source
05Re-embed
06Update FAQ index
Feedback is a proposal, not permission. Only the owner’s approval writes a correction into the bot’s FAQ source file, and the search index is updated from that approved content.
The problem
On an enterprise RAG platform, users could dislike a bot’s answer and supply a corrected response. That feedback was valuable, but it sat outside the knowledge lifecycle. Nothing turned a good correction into an answer the bot could reuse.
Treating every correction as trusted would have been worse. It would put unreviewed text into retrieval and bypass the person who owns the bot’s knowledge.
Owner review. Each bot’s creator owns its knowledge, so a correction needs their explicit approval before it becomes an answer.
A durable source of truth. Approved answers had to live in the bot’s FAQ source file, not only inside a search index.
Re-indexing. An approved change only helps once it is embedded and in the bot’s FAQ index.
Older FAQ files. Bots already had creator-uploaded FAQ files, and the workflow had to stay compatible with them.
How it works
The workflow runs per bot, from a user’s reaction to an updated FAQ index.
Capture. A disliked answer and the user’s corrected response enter a pending queue. Queueing is idempotent, so a repeat does not create a second entry.
Notify. The bot’s creator is notified, and the bot catalogue shows a pending count.
Decide. The owner approves or rejects entries one at a time or in bulk.
Persist. Approved entries are appended to, or update, the bot’s FAQ source-of-truth file, which is persisted in S3.
Re-embed. The workflow enables the bot’s FAQ configuration and triggers the embedding workflow.
Index and record. The bot-specific FAQ index in OpenSearch is updated, and the review decision is marked.
Inspect. Owners can view existing FAQ content and download it as CSV. Each row is labelled creator-uploaded or feedback-approved.
At answer time, high-confidence curated FAQ answers can take a direct retrieval path. That path is part of the retrieval case study.
My scope was feedback capture, the approval queue, notifications, source-of-truth updates, re-embedding and FAQ retrieval. I then hardened the flow in nonprod. The work dates from mid-2026, alongside the platform’s API consolidation and production release validation.
Queue and review. The pending queue with idempotent queueing, plus individual and bulk approve and reject actions.
Owner experience. Creator notifications, pending counts in the bot catalogue, and FAQ viewing with CSV download.
Knowledge update. Append-or-update of approved entries in the S3 source file, then FAQ configuration, the embedding trigger, the OpenSearch FAQ index update and the decision record.
Backward compatibility. A creator-uploaded or feedback-approved label on every row, without breaking older FAQ files that lack it.
Environment hardening. Coordinated fixes across backend, database, OpenSearch, workflow and notification services, described below.
Decisions that mattered
Put review before retrieval
Feedback is a proposal, not permission. A correction enters the curated FAQ source only after the bot owner approves it, so unreviewed text never reaches retrieval.
Keep the source of truth outside the index
Approved entries go into the bot’s FAQ file in S3 first, and the OpenSearch FAQ index is built from that file. The approved answers therefore have a durable record that does not live only in the index.
Make repetition safe
Idempotent queueing and deterministic document IDs mean a repeated job does not multiply approved entries.
Bring the queue to the owner
Notifications and pending counts tell owners that decisions are waiting. Bulk actions let them clear a queue without approving entries one by one.
Label where each answer came from
Every FAQ row is marked creator-uploaded or feedback-approved, so owners can tell their own uploads from approved feedback. Older files without the label still load.
The hard part
Symptom. The workflow passed in dev, then failed in nonprod. It failed for several unrelated reasons, not one.
Diagnosis. I investigated each service boundary instead of patching the first visible error. I found five environment-parity failures:
SQL. A query broke on a nullable array.
Configuration. Environment variables the workflow needed were missing in nonprod.
Schema. A database migration had not been applied.
Document IDs. IDs were non-deterministic, which surfaced as duplicate documents.
Notifications. A notification enum value did not match between services.
Fix. I fixed the nullable-array SQL, added the missing environment variables, resolved the migration and who owns it, made document IDs deterministic and aligned the enum values. That meant coordinated changes across backend, database, OpenSearch, workflow and notification services; no single patch would have been enough.
Verified. The feedback-to-FAQ lifecycle became stable in nonprod. The release process gained a clear environment-parity checklist.
The lesson I kept: in a multi-service workflow, the environment is part of the feature.
Evidence & outcome
The record documents the complete path from feedback to an updated FAQ index, and its hardening in nonprod.
End to end. Capture, queue, notification, decision, source-file update, re-embedding, index update and decision record run as one flow.
Environments. Passed in dev, and stable in nonprod after the five fixes.
Production release. FAQ approval was one of the user journeys I validated end to end in the unified backend’s production release, alongside authentication, chat, feedback and notifications.
Governance. Each correction that becomes knowledge carries a recorded owner decision, and unreviewed changes stay out of retrieval.
The outcome
A governed path from a user’s correction to a reusable FAQ answer: owner approval first, a durable source file second, the search index last. Unreviewed feedback never enters retrieval.
Limits & next steps
Impact is not measured yet. There is no published approval volume, reuse rate or answer-quality change. Those are the metrics to collect next, to connect curation work to user impact.
Curation, not training. This maintains curated knowledge for retrieval. It does not change model weights.
Approval is a gate, not proof. An owner’s approval controls what enters the FAQ. On its own, it does not show that answers improved.
Next use of the signal. The documented retrieval-evaluation approach treats approved corrections as governed evaluation signals. That is a plan, not a result.
Precise about environments. The hardening covered dev and nonprod. The production evidence is release validation of the FAQ approval journey, not usage data.
Based on my documented work record, reviewed October 2026. Industry details are generalized: internal product names, employer code, customer identities, private links and infrastructure identifiers are not reproduced. No approval-volume or answer-quality metrics are claimed for this workflow.
Ranked root-cause hypotheses from infrastructure and AI evidence.
A prototype for diagnosing AI incidents that cross models, prompts, retrieval, tools and infrastructure. Specialist investigators gather evidence in parallel, and the system keeps partial and conflicting evidence instead of forcing one answer.
The problem
An AI incident can start in the model, the prompt, retrieval, a tool or the infrastructure. Infrastructure monitoring and AI traces can each fail or disagree, so a single-source diagnosis is unreliable.
What I did
Implemented a BMAD-based prototype. Infrastructure and AI-trace investigators run in parallel, each with its own retry and circuit breaker. I merge their complete or partial evidence, flag conflicts and rank hypotheses.
Result
A completed prototype that returns ranked root-cause hypotheses, each with confidence and supporting evidence, as structured output for Jira, Slack or automation. Incident metrics are the next step.
SYSTEM AT A GLANCECONCEPTUAL VIEW / NOT INTERNAL TOPOLOGY
01Incident
02Parallel investigators
03Merge evidence
04Detect conflicts
05Rank hypotheses
06Structured RCA
Each investigator has its own retry and circuit breaker, so one failed evidence source does not block the analysis.
The problem
When an AI feature misbehaves, the cause can sit in the model, the prompt, retrieval, a tool call or the infrastructure underneath. The evidence is split between two kinds of observability.
Infrastructure monitoring holds pod health, metrics, logs, events and deployment markers. AI observability holds traces, spans, tool calls, token usage and evaluation scores. Either source can be unavailable, and the two can disagree. A diagnosis built from one of them can be confidently wrong.
Partial failure is normal. One unavailable source should not stall the investigation.
Disagreement is information. Conflicting signals should be shown, not quietly resolved.
The result must be usable downstream. Tickets, chat and automation need structured output, not a paragraph of prose.
How it works
Dispatch. An investigation dispatches specialist investigators in parallel: infrastructure evidence on one side, AI traces on the other.
Isolation. Each evidence-collection path has independent retry and circuit-breaker behaviour.
Evidence model. Complete or partial results from the investigators merge into one evidence model.
Reasoning. The system detects conflicts between infrastructure and AI evidence. It attributes the failure across model, prompt, retrieval, tool and infrastructure layers, and correlates it with recent deployments and model or prompt versions.
Output. Several ranked hypotheses, each with a confidence and its supporting evidence, in a standardized structured format suitable for Jira, Slack or automation.
What I built
Method comparison first. Before implementing the observability and RCA use cases, I compared structured multi-agent development and orchestration approaches, including the BMAD method.
Parallel orchestration. I built the dispatch of infrastructure and AI-trace investigators in parallel, with independent retries and circuit breakers per source.
Evidence merging. I merged complete or partial context into one evidence model, so a missing source reduces coverage instead of ending the run.
Conflict detection. I compared infrastructure and AI evidence and flagged where they disagree.
Hypothesis ranking. I produced multiple ranked hypotheses, each with a confidence and its supporting evidence, attributed across layers and correlated with recent deployments and model or prompt versions.
Standardized RCA output. I standardized the result as structured output that Jira, Slack or an automation step can consume.
The wider pilot. The RCA flow is one use case in a BMAD-based multi-agent pilot I developed, spanning planning, development, review, deployment and incident RCA. I integrated multi-model routing, codebase context and Jira workflows into it.
Decisions that mattered
Preserve partial success
If one evidence source fails, the other still counts. The analysis degrades instead of stopping.
Keep disagreement visible
Conflicts between infrastructure and AI evidence are flagged, not settled by whichever source answered first.
Rank several hypotheses
A ranked list of explanations, each with its evidence, is more honest than one premature diagnosis.
Check what changed
Failures are correlated with recent deployments and model or prompt versions, so a hypothesis can point at a specific change.
Structure over prose
A standardized structured result can feed Jira, Slack or automation without someone re-reading free text.
The hard part
Symptom. The two evidence sources could fail independently, and they could disagree. If the analysis waited on both, one unavailable source would stall it. If it trusted only one, that source would set the conclusion.
Diagnosis. Missing evidence and contradictory evidence are different situations. Missing evidence limits what the analysis can say. Contradictory evidence is itself a finding. Neither should collapse into the same confident answer.
Fix. I gave each investigator its own retry and circuit breaker, so a failed source degrades the result rather than blocking it. The merge accepts partial context. Conflict detection compares the two evidence sets explicitly. The output is several ranked hypotheses with confidence and evidence, not one verdict.
Result. The prototype produces a standardized, structured RCA result that can feed operational workflows, in place of a single unsupported explanation. It has not been benchmarked against a labelled set of incidents.
The lesson I kept: partial evidence is still evidence, and disagreement is a finding.
Evidence & outcome
My work record lists this as a completed prototype implementation, built between May and July 2026. The implementation covers four behaviours:
Partial-failure tolerance. One failed evidence source does not block the analysis.
Cross-layer attribution. Model, prompt, retrieval, tool or infrastructure.
Change correlation. Recent deployments and model or prompt versions.
Usable output. Ranked, evidence-backed hypotheses in one standardized structure.
The outcome
A reusable pattern for diagnosing failures that span models, tools, retrieval and infrastructure, and a foundation for automated incident reporting.
Limits & next steps
A prototype, not a production service. Production maturity, automated-test coverage and diagnostic accuracy are not established.
Confidence is not calibrated. Each hypothesis carries a confidence, but it is not a calibrated probability.
No incident metrics yet. There are no incident-volume or mean-time-to-diagnosis figures. Next I would measure incident count, mean time to diagnosis, recurrence, and how often the top hypothesis matches the confirmed root cause.
Reporting is the next step. The structured output is a foundation for automated incident reporting, not a delivered reporting feature.
Based on my documented work record, reviewed October 2026. Industry details are generalized: internal product names, employer code, incident data, logs, private links and infrastructure identifiers are not reproduced. This account is not an independently audited benchmark.
A governed path from chatbots to long-running agents.
I am designing how open-source DeepAgents runs inside an existing enterprise chatbot platform. The design gives agents plans, sub-agents, checkpoints and approvals, while identity, permissions and audit stay with the platform.
The problem
The platform already handled RAG, tool calls, MCP, guardrails and permissions, one request at a time. Long-running work needs plans, specialist sub-agents, approvals, retries and recovery after failure.
What I did
Designed the integration: the platform as control plane, DeepAgents as execution plane. The design covers a proposed run API and event stream, retrieval as explicit tools, authorization outside the model and a seven-step first slice.
Result
A design outcome, not a production result: an incremental path from RAG chatbots to governed agents that reuses existing identity, RAG, MCP, registry, guardrails and deployment. A first run is not yet validated.
SYSTEM AT A GLANCEPROPOSED DESIGN / NOT A DEPLOYED SYSTEM
01Create run
02Plan
03Authorize tool request
04Approve if sensitive
05Execute & checkpoint
06Stream events
The platform governs; the harness executes. The model may request a tool, but it never decides whether the call is allowed.
The problem
The existing enterprise chatbot platform already supports RAG, tool selection, MCP integration, short-term conversation context, guardrails, permissions and observability. It works as a request-response loop.
That loop is not enough for long-running work. A task that needs a plan, several tools, specialist agents, intermediate artifacts, approvals, retries or recovery after failure does not fit in one request.
The challenge is not to add another agent framework. It is to add a full agent harness, keep the enterprise controls that already work, and avoid a second, disconnected platform.
No regression. Existing chatbot behaviour must keep working.
One governance boundary. Identity, permissions, secrets and guardrails stay where they are.
Reuse, not rebuild. RAG, MCP, the agent registry and deployment are already in place.
How it works
The design uses the open-source Python DeepAgents package as the orchestration layer. It provides planning, filesystem-based context management, sub-agent delegation, human-in-the-loop interrupts, streaming and durable execution on LangGraph foundations.
The harness is an execution dependency inside the existing control plane. It is not a separate security or governance boundary.
Control plane: the platform owns
Agent definitions, versions, ownership, publishing and retirement
Model, prompt and system-instruction configuration
Permissions for RAG sources, MCP servers and custom tools
Secret references, credential context and environment routing
Workspace, artifact, data-retention and sandbox policy
Observability, evaluation and release policy
Execution plane: the harness runs
Plan creation, progress tracking and replanning
Sub-agent delegation with isolated context, then result reconciliation
Permissioned knowledge retrieval and enterprise-tool calls
Run state, checkpoints, retries, cancellation and resume
Approval gates before sensitive actions
Artifacts, streaming events and the final response
Proposed run API. One run resource with seven operations: create a run, read its state, stream its events, cancel, retry, resume, and record a decision on a pending approval.
Event stream. The proposed stream carries plan changes, tool calls, sub-agent activity, approvals, checkpoints, artifacts and terminal status in one stable schema.
Knowledge and MCP. Existing retrieval is exposed as explicit runtime tools: knowledge search, chunk retrieval, FAQ search and source-document lookup. MCP tools resolve through platform policy, which maps user and agent identity to machine-to-machine or user-delegated credentials before execution.
What I designed
My role covers the architecture, integration design, runtime contract, security boundary and first-slice planning.
Responsibility split. I separated control-plane governance from execution-plane orchestration, so each concern has one owner.
Run contract. I defined the proposed run API, the event schema, the state layers and the events sent to observability.
Knowledge as tools. I specified how existing retrieval is exposed as runtime tools and how MCP tools pass through platform policy.
Security boundary. I defined where authorization lives: the platform checks every tool request before it runs, and the model never decides.
First implementation slice. I planned a seven-step slice that proves the pattern end to end before the scope grows.
Implementation of that slice is active. The record does not yet show a validated run, so this page describes the design and what it enables.
Decisions that mattered
Adopt a harness; do not rebuild the platform
DeepAgents already supplies planning, sub-agents, interrupts and durable execution. The platform already supplies identity, RAG, MCP and guardrails. Joining them avoids a second, disconnected platform.
Authorization is outside the model
The model may request an allowed tool. It never decides whether the request is authorized. The platform first validates identity, environment, tool policy, input schema, secrets, network access, filesystem access and approval requirements.
Make retrieval a visible tool call
Exposing retrieval as explicit tools puts every knowledge lookup in the trace and lets each specialist agent use its own sources.
One event schema for every consumer
The UI, Datadog, evaluation services and audit storage read the same trajectory, so none of them is coupled to a specific harness implementation.
Prove a thin slice first
Validate one knowledge tool, one authorized enterprise tool, checkpoints, an approval and full events before expanding scope. Existing chatbots must not regress.
The hard part
The hardest problem is adding durable, long-running execution without weakening control. Two risks shape the design.
Risk 1: a second governance boundary. A new runtime could bring its own idea of who may call what. In this design the harness never authorizes anything. The platform checks every tool request before the call runs.
Risk 2: recovery that repeats actions. Resuming a long run is more than replaying a conversation. If a run stops midway, a naive resume could repeat a tool call that already had an effect. The design persists checkpoints and requires resume without replaying completed side effects.
How it will be verified. The first slice tests both risks directly: interrupt and resume a run, pause a sensitive tool for approval, and confirm existing chatbots behave as before. Until that run is validated, this remains a design claim.
Evidence & outcome
This is active design and implementation. What exists today is the architecture: the responsibility split, the proposed run API and event model, the security boundary and the first-slice plan. The record does not yet show a validated first run or a production deployment.
The first implementation slice is the test of the design:
Configure. Set up an agent with the platform’s existing identity and configuration systems.
Plan and call. Create a run that produces a plan, then calls one knowledge tool and one authorized enterprise tool.
Stream. Stream plan and tool events through the stable API contract.
Recover. Persist checkpoints and resume after interruption without replaying completed side effects.
Approve. Pause a sensitive tool for approval and record the decision.
Observe. Emit model, tool, state, error, approval and artifact events into observability.
Protect. Preserve all existing chatbot behaviour without regression.
The design outcome
A practical migration path from RAG chatbots to governed, long-running agents that reuses existing identity, RAG, MCP, registry, guardrails and deployment infrastructure. It is a design outcome, not a measured production result.
Limits & next steps
Active implementation, not a shipped feature. Until a first run is validated, planning, sub-agents, checkpoints, approvals and resume are what the design enables, not completed platform features.
The API is proposed. The run contract has not yet been exercised by a validated run.
No numbers yet. After the first validated run I would track run success rate, median steps, checkpoint resume rate and tool approval rate.
Evidence to capture. The first implementation change, a run trace, the event schema, the persistence backend, security tests, a checkpoint resume and deployment evidence.
Credit where due. DeepAgents is an open-source project from LangChain. My work is the integration design inside an enterprise platform, not the harness library itself.
Based on my documented work record, reviewed October 2026. This page describes a design in progress. Industry details are generalized: internal product names, employer code, private links and infrastructure identifiers are not reproduced. DeepAgents is referenced as a public open-source project. This account is not an independently audited benchmark.
Making images and videos searchable alongside text documents.
A multimodal knowledge workstream that turned images and videos into searchable text: speech transcription and sampled-frame analysis for video, OCR and visual descriptions for images. Media knowledge could then use the same retrieval platform as text documents.
The problem
Important operational and training knowledge lived in images and videos, which standard document ingestion could not search. Indexed as one opaque file, a video cannot point to the part that answers a question.
What I did
Added image and video connectors. Built video processing that pairs speech transcription with sampled-frame analysis, and image processing that pairs OCR with visual descriptions. Added domain prompts, low-information transcript filtering and source and timing metadata.
Result
Images and videos became retrievable through the same platform as text, with each result traceable to its source file and, for video, its timing. Mixed CSV, PDF, image and video sources were onboarded into one data path.
SYSTEM AT A GLANCECONCEPTUAL VIEW / NOT INTERNAL TOPOLOGY
01Image or video
02Extract text
03Filter low-information text
04Keep source & timing
05Embed & index
06Retrieve segments
Video becomes a speech transcript plus sampled-frame analysis. Images become OCR text plus visual descriptions. Both keep their source, and video keeps its timing, before following the same embedding and indexing path as text documents.
The problem
Some of the product, operational and training knowledge that enterprise bots needed lived in images and videos, not documents. Those files often held little or no machine-readable text.
Standard document ingestion could not search that content. Retrieval works on text, so media had to become text first, without losing where it came from.
Two signals in one video. What is said and what is shown carry different information.
Answers need a place in the video. One opaque video object is a poor retrieval result. Results had to point to meaningful segments.
Not every transcript is worth indexing. Some transcripts carry too little information to help retrieval.
Runtime limits. The processing runtime did not include ffprobe, the usual tool for reading a media file’s duration.
Mixed sources. One onboarding could combine CSV, PDF, image and video files.
How it works
Media gets its own extraction step. After that, its text follows the platform’s standard path into embeddings and the search index.
Connectors. Image and video file formats are accepted as knowledge sources.
Video. Speech is transcribed, and frames sampled from the video are analyzed. The resulting text keeps source and timing context, so retrieval can return a meaningful segment.
Images. OCR extracts any text, and a visual description makes the image searchable by meaning even when it holds little or no text.
Domain prompts. Prompts for media processing are written for the content’s domain.
Filtering. Low-information transcripts are dropped before indexing.
Index. The text is embedded and indexed in OpenSearch with source metadata, so a result traces back to the original file.
The toolchain was Python with Whisper, ffmpeg, OpenCV, OCR, vision models, embeddings, OpenSearch and S3. Image and video handling sits beside the platform’s other format-specific processing for tables, JSON, Markdown, PDFs and YAML.
My scope was video, audio and frame processing, OCR, source metadata, ingestion and quality validation. This was early platform work, in mid to late 2025, when the focus was making enterprise knowledge ingestible and searchable.
Media connectors. Image and video file formats accepted as knowledge sources.
Extraction paths. Transcription plus sampled-frame analysis for video; OCR plus visual descriptions for images; time and source metadata on the output.
Domain prompts. Prompts for media processing written for the content’s domain.
Meaningfulness filter. Low-information transcripts dropped before indexing.
Runtime-safe duration. Duration extraction rebuilt on ffmpeg stderr parsing, with an OpenCV fallback.
Onboarding and quality. Onboarded mixed CSV, PDF, image and video sources, tested response quality and documented the component-level architecture.
Decisions that mattered
Turn media into text that keeps its source
Converting speech, frames and images into text let media use the same embedding, indexing and retrieval path as documents. Source metadata keeps each result traceable to the original file.
Use both speech and frames
A transcript misses what is only shown, and frames miss what is only said. Combining them puts both into the searchable representation.
Return segments, not whole videos
Keeping timing context lets retrieval return a meaningful segment instead of a single opaque video object.
Filter before indexing
Low-information transcripts are removed before indexing, so they do not compete with useful content at retrieval time.
Do not assume the toolchain
When ffprobe was missing, duration came from ffmpeg itself, with an OpenCV fallback. Duration extraction no longer depends on one binary being installed.
The hard part
Symptom. Video processing reads each file’s duration, and the usual tool for that is ffprobe. ffprobe was not available in the processing runtime, so duration extraction could not run there.
Diagnosis. ffprobe is a separate binary from ffmpeg, and the runtime did not provide it. ffmpeg, however, reports a file’s duration in the diagnostic output it writes to stderr.
Fix. I redesigned duration extraction to parse ffmpeg’s stderr output, with an OpenCV-based fallback when that does not yield a duration.
Outcome. Duration extraction no longer requires ffprobe in the runtime, and video sources were onboarded alongside CSV, PDF and image sources. The record has no separate benchmark for this fix.
The lesson I kept: check what the runtime actually provides, and give a critical step a fallback.
Evidence & outcome
The record documents the delivered processing paths, the onboarding and the quality work. It holds no retrieval scores for media, so this page quotes none.
Coverage. Image and video formats were added as knowledge sources, next to the platform’s text formats.
Onboarding. Mixed CSV, PDF, image and video sources were onboarded into the platform’s data path.
Traceability. Indexed media text keeps its source, and video text also keeps its timing.
Quality. Response quality was tested, and the component-level architecture was documented.
Reuse. The processing became reusable components. Images and video are now part of the ingestion platform’s format-specific processing.
The outcome
Images and videos became retrievable through the same platform as text knowledge. Results trace back to the original file and, for video, to its timing.
Limits & next steps
No benchmark. Response quality was tested, but there is no published multimodal retrieval benchmark or accuracy comparison.
Descriptions are interpretations. OCR text and generated visual descriptions are machine readings of the media. The original file remains the evidence.
Explored, not shipped. Separately, I explored Amazon Nova multimodal embeddings for image and text retrieval and platform fit. That was an evaluation; the delivered path converts media into text before embedding.
Next: measure it. The natural next step is the platform’s documented evaluation approach: golden records, retrieval scored apart from generation, and citation quality. No media results exist yet.
A 2025 workstream. Later ingestion and retrieval improvements are covered in their own case studies.
Based on my documented work record, reviewed October 2026. Industry details are generalized: the workstream’s internal name, employer code, customer identities, private links and infrastructure identifiers are not reproduced. No media retrieval benchmark is claimed.
One ML monolith, two independently deployable services.
An internal leak-detection application ran its UI, PyTorch model, S3 storage and human review in one Flask process. I split it into a ResNet18 inference service and a lighter review UI. Every image now lands in S3 before the model runs, and I deployed and validated the flow in nonproduction.
The problem
One Flask process loaded the PyTorch model and also served the UI, S3 storage and human review. That coupled resources, enlarged the container image, raised deployment risk and made the UI costly to scale apart from inference.
What I did
Split it into a ResNet18 inference service (prediction, health, metrics) and a UI service that never imports PyTorch. Changed uploads to stage in S3 before inference. Fixed a crash loop and IRSA credential discovery.
Result
Both services deployed independently in nonproduction. The end-to-end smoke test passed: S3 staging and finalization, model invocation and a representative leak prediction. The final UI deployment had zero restarts.
SYSTEM AT A GLANCECONCEPTUAL VIEW / NOT INTERNAL TOPOLOGY
01Upload or capture
02Stage in S3
03Inference API
04Human review
05Finalize in S3
The image is saved before the model runs. If inference fails, the staged image stays in S3 instead of being discarded.
2independently deployable services, split out of one Flask process
0restarts in the final UI deployment at the recorded validation point
0.531confidence on a representative leak image in the smoke test (proves the path, not accuracy)
The problem
An internal leak-detection application uses a ResNet18 computer-vision model to predict leaks from images, with human review of the predictions.
The original Flask application did everything in one process. It loaded the PyTorch model, served the UI, moved images in S3 and handled human review. Parts with very different resource needs shared one container image and one deployment.
Coupled resources. The UI carried the model’s dependencies, which enlarged the image and tied UI resources to inference.
Deployment risk. A change to either part meant redeploying both.
Scaling cost. The UI could not scale separately from inference.
Uploads are evidence. A failed prediction must not lose the image a user just submitted.
How it works
The application is now two services with an HTTP boundary between them.
Inference service. Loads the ResNet18 checkpoint and exposes prediction, metrics and health endpoints. It is the only service that needs PyTorch.
UI service. Handles upload, webcam capture, human review, S3 movement and lightweight tracking. It calls the inference service over HTTP and never imports PyTorch.
S3-first path. Every image is staged in S3 before inference and finalized in S3 after review. If inference fails, the staged object is kept.
Deployment. The services run on TrueFoundry and Kubernetes. IRSA provides the AWS credentials, and the deployment exposes a stable service hostname.
What I built
My scope was the service decomposition, the inference API, S3-first durability, IRSA troubleshooting and runtime validation.
Service split. I separated the model from the UI and introduced the HTTP inference boundary between them. The UI service no longer imports PyTorch.
Inference API. Prediction, health and metrics endpoints around the ResNet18 checkpoint.
S3-first staging. I changed the upload path so every image lands in S3 before inference, and kept the staged object when inference fails.
Runtime fixes. I fixed a crash loop, made IRSA credential discovery explicit and exposed a stable service hostname.
Validation. I ran the end-to-end smoke test and checked the final UI deployment for restarts.
Decisions that mattered
Separate the model from the interface
The UI and the model have different resource needs. Keeping PyTorch only in the inference service lets each one deploy and scale on its own.
Put inference behind HTTP
An inference API with health and metrics endpoints makes the model a service that can be checked and deployed without touching the UI.
Save the input before running inference
Staging in S3 first means a model error does not cost the user their image. The staged object stays as evidence instead of being discarded.
Make cloud identity explicit
I configured the web-identity token path explicitly instead of relying on discovery defaults. Paths and identity are part of the runtime contract.
The hard part
Symptom. Two runtime failures stood between the split and a working deployment. One service was stuck in a crash loop, and IRSA credential discovery failed, so the S3 path could not get AWS credentials.
Diagnosis. The crash loop traced to a data-directory mismatch. The credential failure was in discovery: the web-identity token that IRSA relies on was not being picked up.
Fix. I fixed the data-directory mismatch. I configured the web-identity token path explicitly, so credential discovery no longer depended on defaults. I also exposed a stable service hostname.
Verified. The end-to-end smoke test confirmed S3 staging and finalization, model invocation and a representative leak prediction with confidence 0.531. The final UI deployment showed zero restarts.
The lesson I kept: file paths and cloud identity are part of the runtime contract, not deployment details to sort out later.
Evidence & outcome
I deployed and validated the flow in nonproduction. The checks:
Independent deployment. The UI and inference services deployed independently.
End-to-end path. The smoke test confirmed S3 staging, model invocation and S3 finalization.
Model call. A representative leak image returned a leak prediction with confidence 0.531.
Stability. The final UI deployment had zero restarts at the recorded validation point.
The outcome
The UI can now deploy and scale without the model, uploaded images survive inference failures, and the split is a repeatable pattern for model-backed internal applications.
Limits & next steps
Nonproduction. I deployed and validated the flow in nonproduction. This account does not claim a production rollout or production traffic.
A smoke test, not a model evaluation. 0.531 is the confidence of one representative prediction. It shows the path works. It is not accuracy, precision or recall, and no model-quality metric is claimed here.
Point-in-time stability. The zero-restart count was recorded at validation. It is not a long-term uptime figure.
Scaling is enabled, not measured. No latency, throughput or load-test figures are claimed.
What I would measure next. Model quality on a labelled image set, inference latency and error rates, and restarts over a longer window.
Based on my documented work record, reviewed October 2026. The application is described generically; its internal name, proprietary code, service hostnames and infrastructure identifiers are not reproduced. Results come from a nonproduction smoke test, not an independently audited benchmark.
Fewer services, unblocked repositories, same authentication checks.
I moved about 14 onboarding capabilities into one backend and validated the main user workflows in production. I also removed a hard-coded allowlist that blocked every new GitHub repository, without weakening OIDC verification.
The problem
Onboarding ran in a separate service with its own token handling, and users lacked consistent analytics and progress visibility. A hard-coded allowlist made GitHub connector workflows fail for every newly onboarded repository.
What I did
Moved about 14 capabilities into the unified FastAPI backend on shared session authentication, keeping the UI’s response contracts. Added analytics and progress states. Removed the allowlist but kept the OIDC claim checks, then repaired the deployment pipeline.
Result
One onboarding backend, validated end to end in production from Okta sign-in to re-ingestion. Previously blocked repositories authenticated successfully in dev, nonprod and prod, with no redeploy.
SYSTEM AT A GLANCECONCEPTUAL VIEW / NOT INTERNAL TOPOLOGY
01Shared session auth
02Unified backend
03Onboarding workflow
04Index & storage
05Progress & failure alerts
Onboarding now runs in the same backend and session model as chat. GitHub connector workflows are accepted on verified OIDC claims, not on a list of repositories.
~14onboarding capabilities moved into one backend
3environments where previously blocked repositories were verified: dev, nonprod, prod
The problem
Onboarding capabilities ran in a separate service with its own token handling, apart from the unified chatbot backend. Users lacked consistent analytics and progress visibility for long-running onboarding jobs.
Operations had their own failure modes. New sources and long-running workflows exposed hard-coded authorization, credential expiry, OpenSearch shard pressure and environment-specific deployment failures. Many defects came from environment configuration, routing or authentication rather than application logic.
Keep the UI working. The portal depended on existing response contracts. The implementation could move; the contracts could not change.
Keep authentication strength. Removing an onboarding bottleneck could not weaken enterprise controls.
Hold up in every environment. A change had to work in dev, nonprod and prod, each with its own configuration, secrets and deployment state.
How it works
After the migration, onboarding and chat share one backend and one session model.
One session model. Onboarding routes use the platform’s shared session authentication instead of custom token handling.
One backend. The migrated routes follow the receiving service’s async database and HTTP patterns. Agent and MCP schemas are owned in the same codebase.
Visible workflows. Long-running onboarding jobs report progress and completion states. A failure in any workflow stage reaches the user through one notification path.
Environment-aware indexing. OpenSearch shard and replica counts come from environment configuration. Concurrent index creation is idempotent, and a failed creation reports the real error.
Claim-based triggers. A repository’s GitHub Actions workflow can trigger a knowledge update with an OIDC token (see enterprise connectors). The service checks the issuer, the signature against published keys (JWKS), the audience and the repository claim.
What I built
Onboarding API migration. I moved about 14 capabilities from a separate service into the unified backend. I adapted async database and HTTP patterns to the receiving service and replaced custom token handling with shared session authentication. Response contracts for the UI stayed the same. I also moved agent and MCP schema ownership into the unified codebase.
Analytics dashboard. I built a dashboard with usage totals, per-bot breakdown, daily trends and filters. I resolved backend routing and a nonprod runtime blocker so the portal consumed the correct API.
Onboarding experience. I added clearer progress and completion states for long-running jobs, plus file deletion, manual refresh and download of existing FAQs.
Stable identifiers. I standardized internal bot identifiers while keeping user-friendly display names.
OIDC without an allowlist. I removed the hard-coded repository allowlist, kept the OIDC claim checks and repaired the deployment pipeline the fix depended on. The hard part below has the detail.
Long-running upload reliability. I added proactive AWS credential refresh with retry on expired-token errors, centralized failure notifications, environment-specific shard configuration and idempotent index creation. The knowledge platform case study covers these in context.
Ephemeral runner design. I designed a self-hosted runner model that creates a pod, runs the job, cleans up and centralizes repository access.
Release validation and support. I executed the end-to-end production release validation. In production support I diagnosed issues across chat, connectors, authentication and deployment.
Decisions that mattered
Move the implementation, keep the contract
I moved code and schema ownership but kept the response contracts the UI relied on. Consolidation should not force a frontend rewrite.
One way to authenticate
Shared session authentication replaced custom token handling. That leaves one authentication path to secure and validate instead of two.
Verify claims, not a list
A hard-coded allowlist turns every new repository into a redeploy. Issuer, signature, audience and repository-claim checks keep authentication strength without knowing every repository in advance.
Test journeys, not just endpoints
Many defects lived in configuration, routing or authentication. So release validation walked real user workflows through the deployed platform, not code in isolation.
Summarize incidents, don’t just link them
A link to a support conversation is not reusable operational knowledge. An incident should be written up as symptom, impact, root cause, fix and verification, which is how the hard part below is told.
The hard part
Symptom. Authenticated GitHub connector workflows failed for every newly onboarded repository. A new repository could not trigger the service unless the service was redeployed.
Impact. Onboarding a GitHub source needed a manual gate: a code change and a redeploy.
Root cause. The requests were authenticated. They were rejected by a hard-coded repository allowlist, which tied every new source to a deployment.
Fix. I removed the allowlist enforcement and kept issuer, signature (JWKS), audience and repository-claim validation.
A second problem. Shipping the fix needed a deployment path that had not been exercised for months. Validation surfaced accumulated faults: internal package installation, expired platform tokens, stale CLI state on persistent runners, incorrect secret names and missing secret permissions. I repaired each one, so the work restored the pipeline as well as the feature.
Verified. In dev, nonprod and prod, authenticated workflows from previously blocked repositories succeeded. The issuer, signature, audience and repository-claim checks stayed in place.
The lesson I kept: a deployment path nobody exercises is a hidden dependency of every fix.
Evidence & outcome
The delivery record documents the API migration, the production release validation and the OIDC change. Repositories that were never on the allowlist triggered the service in dev, nonprod and prod with the same claim checks.
Production release validation. End to end through the deployed platform: Okta authentication, bot listing, chat, feedback, notifications, FAQ approval, access requests, source refresh and re-ingestion.
A working deployment path. The pipeline that had sat unused for months could deploy again.
Diagnosable failures. Errors from any workflow stage reach one notification path, and failed index creation reports the real OpenSearch error.
The outcome
Less fragmented platform operations: one onboarding backend on shared authentication, new repositories without a redeploy, and failures that show their real cause.
Limits & next steps
No uptime or incident metrics. I do not claim an uptime, incident-reduction or time-to-diagnosis figure. Next I would track incident count, mean time to diagnosis and recurrence.
Incident write-ups are a follow-up. Next I would turn past support cases into reusable summaries with impact, root cause, remediation and verification.
Authentication is not an authorization review. Keeping the OIDC checks preserved authentication strength. It does not replace a complete authorization review.
The runner model is a design. I designed the ephemeral runner model; I do not claim it is running in production.
Shared platform work. This is my part of a team platform, not a claim of sole ownership.
Based on my documented work record, reviewed October 2026. Industry details are generalized: internal product names, employer code, customer identities, repository and secret names, private links and infrastructure identifiers are not reproduced. This account is not an independently audited benchmark.
Industry research & developmentCompleted2023 - 2024
Forecasting HVAC power use from noisy building sensors.
At WattWorker I built models that forecast HVAC power consumption for three commercial buildings in the UK and US. I paired them with physics-informed models of indoor temperature, and built supervised-learning models for EV battery remaining useful life and range.
The problem
Forecast HVAC power consumption and model indoor-temperature dynamics for three commercial buildings, from noisy sensor data, to inform control and operational insights.
What I did
Developed RNN, CNN, XGBoost, Random Forest and H2O AutoML forecasting models and improved them through hyperparameter optimization. Built thermodynamic models with physical equations and curve fitting.
Result
Reported model performance improved from 78% to 94% through hyperparameter optimization. I presented control and operational insights to stakeholders.
Stack
PythonRNNsCNNsXGBoostRandom ForestH2O AutoML
SYSTEM AT A GLANCECONCEPTUAL VIEW / NOT INTERNAL TOPOLOGY
01Building sensor data
02Preparation
03Model families
04Hyperparameter optimization
05Operational insight
Data-driven forecasts of HVAC power use, with physics-informed models of indoor temperature alongside them.
78% → 94%reported model performance for HVAC forecasting, through hyperparameter optimization
3commercial buildings across the UK and US supplied the sensor data
5modelling approaches developed: RNN, CNN, XGBoost, Random Forest and H2O AutoML
The problem
From 2023 to 2024 I worked at WattWorker Inc. as a Machine Learning Research and Developer. I worked on HVAC power consumption in commercial buildings, and on EV battery and telemetry data.
The data came from sensors in three commercial buildings across the UK and US, and it was noisy. The modelling fed control and operational insights that I presented to stakeholders.
Noisy sensors. Models had to learn from imperfect measurements.
Two kinds of question. How much power HVAC will use, which suits data-driven forecasting, and how indoor temperature changes, which has physical dynamics behind it.
A second domain. EV battery remaining useful life and range, plus GPS telemetry from vehicles.
How the work fit together
The work ran as three strands.
HVAC power forecasting. Building sensor data feeding several model families: RNN and CNN neural networks, XGBoost and Random Forest tree ensembles, and H2O AutoML. Hyperparameter optimization on top.
Indoor-temperature dynamics. Physics-informed thermodynamic models built from physical equations, with curve fitting to match them to the data.
EV battery and telemetry. Supervised-learning models for battery remaining useful life and range, plus GPS telemetry analysis for route, trip and operational patterns.
What I built
Forecasting models. RNN, CNN, XGBoost, Random Forest and H2O AutoML models for HVAC power-consumption forecasting.
Hyperparameter optimization. Tuning that improved reported model performance from 78% to 94%.
Thermodynamic models. Physical equations and curve fitting to estimate indoor-temperature dynamics.
Stakeholder insight. I presented control and operational insights from the modelling to stakeholders.
EV battery models. Supervised-learning models for remaining useful life and range prediction.
Telemetry analysis. GPS telemetry analysis for route, trip and operational patterns.
Decisions that mattered
Compare model families
Explore neural, tree-based and AutoML approaches rather than choosing a model before examining the data.
Invest in tuning
Treat hyperparameter optimization as part of the modelling work, not a final step. It is where the reported gain came from.
Use physical context
Model indoor-temperature dynamics with thermodynamic equations alongside learned relationships, and fit them to the data.
Connect to operations
Turn modelling results into control and operational insights for stakeholders, and analyze GPS telemetry for route and trip patterns.
The hard part
Problem. The sensor data was noisy, and the system behind it has physical behaviour of its own. Noisy measurements and physical-system behaviour had to be considered together.
Approach. I worked from two sides. On the data side, I developed several model families for HVAC power forecasting and improved them through hyperparameter optimization. On the physics side, I built thermodynamic models from physical equations and fitted them to data with curve fitting.
Result. Reported model performance for HVAC forecasting rose from 78% to 94%. The physics-informed models gave an estimate of indoor-temperature dynamics, and I presented control and operational insights to stakeholders.
The lesson I kept: on physical systems, empirical modelling works best next to an understanding of the system being measured.
Evidence & outcome
Forecasting. Reported model performance for HVAC power-consumption forecasting improved from 78% to 94% through hyperparameter optimization.
Scope. Sensor data from three commercial buildings across the UK and US.
Operations. Control and operational insights presented to stakeholders.
EV work. Supervised models for battery remaining useful life and range, and GPS telemetry analysis of route, trip and operational patterns.
The outcome
Tuned HVAC forecasting models, physics-informed indoor-temperature models and EV battery models, with the findings presented to stakeholders as control and operational insights.
Limits & next steps
The metric is reported, not defined here. 78% and 94% are reported model performance. This page does not state the metric, the data split or the baseline, so I do not present them as an accuracy figure.
No public artifacts. Datasets, code and building identities are not published, and there is no reproducible benchmark.
No EV metrics. This account reports no outcome metrics for the battery or telemetry work.
Not a publication. This was industry research and development, not peer-reviewed research.
What a reproducible version needs. The metric definition, the data split and a baseline, published with the results.
Based on my resume and documented work record, reviewed October 2026. Building identities, datasets and proprietary code are not reproduced. The performance figures are as reported in that record, not an independently audited benchmark.
Why agent discovery and agent execution belong behind different contracts.
Swaroop Chand J COctober 20264 min read
An agent catalogue answers a useful question: what is available? It does not, by itself, answer where an agent runs or how to execute it. Keeping those questions separate was an important part of my agent-platform work.
Two responsibilities, two boundaries
A registry describes the agent: its purpose, owner, capabilities, lifecycle state, and the information needed to locate it. A runtime executes work. Combining them too tightly means that adding a specialist agent can become a platform migration instead of a registration task.
The compatibility decision
In the implementation described in my case study, an entry with an endpoint could route to an independently deployed service. Entries without endpoints retained the existing built-in execution path. That distinction let the platform add a new execution model without forcing every current agent to move.
The hard part is the contract
A working endpoint is only one part of the boundary. The platform still needs to resolve identity, enforce access, handle a failed call, and turn the result into something the user can inspect. Streaming tool events were especially useful for making the research agent's work visible.
A failure that changed the design
The web-search path worked locally but failed from the deployed environment. The issue was upstream treatment of datacenter egress, not the agent's reasoning. A three-stage search fallback and explicit diagnostics made that distinction visible. An empty upstream result should not quietly become an answer.
What I would measure next
The next useful evidence is not the size of the catalogue. It is whether registered agents can be discovered, invoked, updated, and retired reliably, with clear ownership and observable errors. The supplied project record does not include a published lifecycle-reliability benchmark.
THE TAKEAWAY
Centralize discovery and lifecycle. Make execution an explicit, observable boundary.
Adapted from documented project work. Examples are generalized, and proposed evaluations are identified as proposals rather than reported results.
ENGINEERING NOTE / Data infrastructure
Parallelism is not a memory strategy.
A faster ingestion pipeline can still fail when every worker holds too much data.
Swaroop Chand J COctober 20264 min read
Parallel document processing reduced elapsed time in two recorded workloads. Five PDFs went from 10 to 6 minutes; forty went from 118 to 81 minutes. Those results were useful, but they were not the end of the scaling problem.
What the measurements actually say
The measurements describe those particular PDF workloads. They do not prove a fixed speedup for every format, document size, parser, or execution environment. Keeping the workload beside the number is part of making the result meaningful.
The other axis of scale
A separate customer-storage test exposed a different failure: documents accumulated in an in-memory list. Adding more workers does not automatically bound how much each worker retains. A pipeline can finish a small input faster and still fail on a larger input.
The boundary worth changing
The documented follow-up is streaming or generator-based fetching: obtain a document, process it, release its working data, and then move on. That design has to be checked across extraction, chunking, embeddings, and indexing; a downstream stage can reintroduce the same accumulation.
A better next experiment
I would compare the list-based and streaming approaches on a fixed public workload, measuring peak memory, elapsed time, documents completed, and failures. Document size and format should be recorded, and repeated runs should be reported rather than only the fastest run. This is a proposed evaluation, not a completed benchmark.
Failure visibility still matters
The workflow modernization also added explicit stages and centralized failure notification. A throughput number is not enough when a failed stage leaves the user waiting without knowing whether the job is still running.
THE TAKEAWAY
Measure elapsed time and peak memory separately. Speed is not the same as a bounded working set.
Adapted from documented project work. Examples are generalized, and proposed evaluations are identified as proposals rather than reported results.
ENGINEERING NOTE / Human-in-the-loop systems
A correction is not knowledge. Yet.
Designing the boundary between user feedback and trusted retrieval.
Swaroop Chand J COctober 20264 min read
A user correction is valuable input. It is not automatically an approved answer. My feedback-to-FAQ work made that distinction an explicit part of the platform rather than an assumption inside a prompt.
Start with a proposal
The correction enters a pending queue and the bot owner receives a notification. The owner can approve or reject entries individually or in bulk. Until that decision is made, the proposal is not part of the curated FAQ source.
Keep the durable record separate
Approval updates the persistent source of truth and triggers the re-embedding workflow. The search index is then updated from that approved content. This separation gives the workflow a durable record to revisit when indexing fails or needs to run again.
Make repeated execution boring
Repeated jobs exposed why deterministic document identifiers and idempotent queueing matter. Running the same work again should not silently multiply the approved entries. Source classification also distinguishes creator-uploaded content from approved feedback.
The environment is part of the feature
The nonproduction rollout revealed nullable-array SQL problems, missing configuration, an unapplied migration, and notification-category mismatches. Fixing only the first visible exception would have left the end-to-end workflow broken.
Be precise about learning
This is a governed knowledge-curation loop. It is not model-weight training, and approval alone does not establish a measured answer-quality improvement. The next useful evidence would connect review volume, retrieval reuse, and evaluation results.
THE TAKEAWAY
Capture freely. Review explicitly. Update a durable source before refreshing retrieval.
Retrieval tuned per source, not one global setting.
I improved the path from document structure to grounded answers on an enterprise RAG platform: chunking, hybrid retrieval, per-source controls and product-support answer quality. Retrieval became configurable by source and use case, with standard hybrid search as the fallback.
The problem
Bots answered from prose, tables, YAML, JSON and media, across sources such as SharePoint and Confluence, and in German and English. One chunking strategy and one global retrieval setting could not serve them all.
What I did
Implemented semantic and format-specific chunking, cosine/Manhattan/combined vector modes, per-source Top-K, metadata filters and a direct FAQ path. Investigated a German/English retrieval mismatch and tuned a product-support assistant’s answers.
Result
Retrieval is configurable by source and use case instead of one global setting. Bots without advanced configuration keep standard hybrid search, and high-confidence curated FAQ answers take a direct path.
SYSTEM AT A GLANCECONCEPTUAL VIEW / NOT INTERNAL TOPOLOGY
01Chunk by structure
02Filter by metadata
03Retrieve per source
04Rerank
05Answer with sources
Top-K is set per source, the vector mode is configurable, and every control is optional. Without advanced configuration, standard hybrid search runs as before. High-confidence curated FAQ answers can take a direct path.
The problem
An enterprise RAG platform serves many bots, and each draws on different content: prose documents, tables, YAML, templates, JSON and multimodal content. It arrives from SharePoint, Confluence, the web and other sources.
A single chunking strategy cannot serve all of that equally well. A single global retrieval setting has the same problem. Creators needed to take different amounts of evidence from different sources, and to restrict a bot to the documents that matter for it.
Language added another axis. Equivalent questions in German and English did not always retrieve the same evidence.
Do not break existing bots. Advanced retrieval had to be opt-in, with current behaviour as the fallback.
Keep answers traceable. Source references and citations had to survive chunking and ranking.
Make quality diagnosable. A bad answer can come from retrieval or from generation, so the two had to be measured apart.
How it works
The work spans three layers: how content is chunked, how evidence is retrieved and how the answer uses it.
Chunking. Semantic boundaries with overlap, language-aware model selection, and format-specific bypasses so structured content such as tables keeps a structural split.
Hybrid retrieval. Dense vector search and sparse BM25 search, with rank fusion and cross-encoder reranking. Standard hybrid search stays the default when no advanced configuration is set.
Vector modes. Cosine, Manhattan or combined vector retrieval, chosen as configuration.
Per-source Top-K. A bot can take a different number of results from SharePoint, Confluence, the web or other sources.
Metadata filters. Retrieval can be restricted to a relevant subset of documents.
Direct FAQ path. High-confidence curated answers are retrieved directly. FAQ entries are creator-uploaded or owner-approved feedback, never raw, unreviewed feedback.
Answer layer. For a product-support assistant: grounding, alternative-product handling, localization and source references.
Format-specific extraction upstream of all this is part of the ingestion case study.
Chunking, from evaluation to production. I compared chunking strategies and tested them on a security-focused bot’s content. I then integrated semantic boundaries and overlap, and added language-aware behaviour and format-specific bypasses.
Retrieval controls. I implemented multi-metric vector retrieval, per-source Top-K, metadata filtering and the FAQ bypass.
Hybrid retrieval. I engineered hybrid retrieval with dense and sparse search and cross-encoder reranking. When a bot sets no advanced options, standard hybrid search runs as the backward-compatible fallback.
Product-support answer quality. For a product-support assistant, I improved grounding, alternative-product handling, localization, source references and the response behaviour stakeholders asked for.
Multilingual analysis. I investigated why equivalent German and English queries retrieved differently, and documented the options to close the gap.
Multimodal embedding evaluation. I explored Amazon Nova multimodal embeddings for image and text retrieval and their fit with the platform. This was an evaluation, not a shipped feature.
Chunking and quality work on a security-focused bot came first, in mid to late 2025. The retrieval controls followed in early 2026.
Decisions that mattered
Match the chunker to the content
Prose gets semantic boundaries with overlap. Structured formats bypass semantic splitting. No single strategy serves prose, tables, YAML, templates, JSON and multimodal content equally well.
Configure per source, not globally
Top-K per source and metadata filters let a bot draw the right amount of evidence from each source, instead of inheriting one global setting.
Keep hybrid search as the fallback
Advanced configuration is opt-in. A bot without it keeps standard hybrid search, so existing bots keep their behaviour unless a creator opts in.
Give curated answers a direct path
A direct FAQ retrieval path serves high-confidence curated answers. Those entries are uploaded by the creator or approved by the owner through the feedback workflow.
Measure retrieval and generation apart
A wrong answer can come from missing evidence or from how the model used it. Scoring the two separately makes the root cause measurable.
Symptom. Semantically equivalent questions in German and English could retrieve different evidence. The same question could be grounded differently depending on the language it was asked in.
Diagnosis. The investigation tied the difference to a mismatch between the language of the indexed content and the language of the query.
Options. The documented solution space has three approaches, each acting at a different point:
Query translation. Translate the question into the language of the indexed content before retrieval.
Multilingual embeddings. Embed queries and content in a space shared across languages.
Synonym and domain dictionaries. Map equivalent terms across languages and domain vocabulary.
Status. This is an investigation with documented options, not a shipped fix. Choosing between them needs a multilingual comparison: the same question set in both languages, scored on the evidence each one retrieves.
The practical takeaway: when equivalent questions retrieve differently, check whether the query and index languages match before tuning ranking.
Evidence & outcome
This work was delivered across multiple iterations on the platform. The evidence is the shipped behaviour, not a benchmark score.
Configurable retrieval. Vector mode, per-source Top-K and metadata filters make retrieval configurable by source and use case.
No forced migration. Bots without advanced configuration keep standard hybrid search.
Curated answers. High-confidence FAQ answers take a direct retrieval path.
Product-support answers. Grounding, alternative-product handling, localization and source references improved for a product-support assistant.
The documented evaluation approach is designed to make that quality measurable:
Golden records. Compare expected answers and retrieval evidence against curated datasets.
Two scores, not one. Score retrieval quality separately from generation quality.
Attribution and format. Track source attribution, citation quality and answer formatting, including tables and rich text.
Governed signals. Use user feedback and approved corrections as evaluation and learning signals, not as unreviewed truth.
The outcome
Retrieval became more controllable, traceable and adaptable to each content source, instead of depending on one global setting. Relevance improved across iterations, but it has not been scored on a golden set, so I quote no quality numbers.
Limits & next steps
No quality numbers yet. The record has no verified Recall@K, groundedness or citation-accuracy figures. Those, plus a multilingual comparison, are the next metrics to collect on a golden set.
Multilingual is investigated, not solved. Query translation, multilingual embeddings and dictionaries are documented options, not shipped features.
Explorations are not features. The multimodal embedding work was an evaluation of platform fit, not a production retrieval path.
Shared platform. This is my part of a team platform, described in general terms.
Based on my documented work record, reviewed October 2026. Industry details are generalized: internal product names, employer code, customer identities, private links and infrastructure identifiers are not reproduced. This page quotes no retrieval-quality scores because the record holds no verified ones; it is not an independently audited benchmark.
Enterprise sources that stay in sync, deletions included.
Connectors that bring GitHub, Confluence, Workday, SharePoint and S3 content into an enterprise RAG platform. My part was the connector contracts, authentication, pagination, change detection and deletion, so a source can be refreshed instead of uploaded once and left to go stale.
The problem
Knowledge lived in code repositories, wikis, HR help content and storage buckets, each with its own API, credentials, update rules and metadata. A one-off upload could not follow updates or deletions, and every new source became its own copy project.
What I did
Built GitHub ingestion and an OAuth2 Workday connector with pagination, and improved Confluence traversal and table extraction. Added SHA-256 change detection, deletion propagation, repository-isolated S3 paths and source URLs for traceable answers.
Result
Workday validation fetched about 1,145 published help articles; new, updated and deleted articles are detected and stale vectors removed. Files deleted from a repository are removed from the index too.
SYSTEM AT A GLANCECONCEPTUAL VIEW / NOT INTERNAL TOPOLOGY
01Authenticate
02Fetch & paginate
03Detect changes
04Embed new & updated
05Remove deleted
06Index with source URL
Each source authenticates and pages through its API in its own way. Incremental sync then applies what changed, removes what was deleted and keeps the source URL with the content.
~1,145published Workday help articles fetched during connector validation
59,202objects listed when validating the customer-owned S3 connector
The problem
The knowledge behind the platform’s bots lived in many systems: code repositories, Confluence wikis, Workday help content, SharePoint documents and S3 buckets. Each source has its own API, credentials, update semantics and metadata.
Static uploads made this worse. A one-off copy goes stale as soon as the source changes, and each new source turned into its own manual data-copy project.
Freshness in both directions. A refresh has to add new content, update changed content and remove deleted content.
Isolation. Several repositories can be onboarded together. Cleaning up one source’s deleted files must never touch another source’s content.
Traceability. Answers need a source URL and attribution that point back to the original page, article or file.
How it works
Each connector owns the source-specific part: authentication, fetching and pagination. Its documents then flow, with their source URL and attribution, into the shared chunking, embedding and OpenSearch indexing pipeline.
Incremental sync adds three pieces:
Change detection. SHA-256 change detection flags new and updated content. The Workday connector also keeps CSV metadata snapshots and compares each run against the last one.
Deletion. Content removed at the source is deleted from the vector store, so the index reflects the source instead of accumulating stale documents.
Isolation. Each repository writes to its own S3 path, so one source’s sync cannot delete another source’s content.
GitHub updates can start from the source side: a GitHub Actions workflow triggers the update, authenticated through OIDC. Opening that trigger to newly onboarded repositories is a platform reliability story.
My role covered connector contracts, authentication, pagination, change detection, deletion, metadata and end-to-end integration. The status word on each source is the one my record uses.
GitHub: built. Recursive repository ingestion into repository-isolated S3 paths, with deleted-file propagation to the vector index. Source URLs and repository attribution stored in OpenSearch. Multi-repository onboarding that keeps single-repository setups working, and updates through OIDC-authenticated GitHub Actions triggers.
Confluence: improved. Label-based filtering for targeted onboarding. Recursive descendant fetching, so nested pages are not silently missed. Structured table extraction, so tables stay useful to RAG instead of collapsing into unreadable text. Source-URL traceability.
Workday: built. An OAuth2 connector with pagination and article extraction that keeps each article’s source URL. CSV metadata snapshots drive incremental comparison: new, updated and deleted articles are detected, and stale vectors removed.
Change detection: added. SHA-256 change detection and stale-record deletion, so vector stores stay aligned with new, updated and removed content.
SharePoint: supported. Enterprise document onboarding and expanded file-format compatibility.
S3: supported, then customer-owned. I supported internal uploads, and later introduced customer-owned buckets with isolated credentials. That work has its own case study.
Slack: designed. An authorized channel-content ingestion pattern, with scoping and deletion concerns documented.
Jira MCP: explored. Conversational issue operations, and the credential storage, field allow-lists, user permissions and audit requirements they would need.
Snowflake MCP: integrated. Governed data access for an enterprise assistant, covered with the agent platform.
SharePoint onboarding came first, in mid to late 2025. The Git, Confluence and Workday connectors and the Jira MCP exploration followed in early 2026. Multi-repository Git and customer-owned S3 came in August to September 2026.
Deletion sync is only safe when each source owns its storage. Repository-specific paths mean one repository’s sync cannot delete another’s content.
Compare against the last known state
Sync compares each run with what was ingested before: SHA-256 hashes for content changes and, for Workday, a CSV metadata snapshot. That separates new, updated and deleted items.
Keep the source URL with the content
Source URLs and repository attribution are stored in OpenSearch with the text, so an answer can point back to its page, article or file.
The hardest problem here was a design risk rather than one incident: making deletion safe.
The failure mode. Without deletion sync, a refreshed index keeps everything it has ever seen. Files removed from a repository and deleted help articles stay retrievable as if they were current.
Why the obvious fix is risky. Deleting whatever is missing from the latest fetch is safe only if the connector knows exactly what it owns. With several repositories onboarded, cleanup against shared storage could remove another source’s content.
What I built. I gave each repository its own storage path, so the deletion scope is one repository. On top of that I added deleted-file propagation for GitHub, and snapshot-based new/updated/deleted detection with stale-vector removal for Workday.
The quieter failure. Content that is never fetched is just as wrong as content that is never deleted. In Confluence, I improved recursive descendant fetching so nested pages are not silently missed.
Checked. Workday incremental ingestion was validated against about 1,145 published help articles. The concrete incident from this work, a hard-coded repository allowlist that blocked OIDC-authenticated triggers, is told in the platform reliability case study.
The lesson I kept: a connector is not finished when it can fetch. It is finished when it can delete safely.
Evidence & outcome
Workday. About 1,145 published help articles fetched during connector validation, with incremental ingestion validated against them.
Customer-owned S3. 59,202 objects listed in that connector’s validation.
Coverage. Platform knowledge now spans Confluence, SharePoint, GitHub, Workday and S3 sources.
Knowledge onboarding became a reusable platform capability rather than a series of manual data-copy projects. Sources can be refreshed instead of re-uploaded, and deleted-document cleanup keeps the index closer to the source.
The outcome
Sources that refresh instead of going stale, content that keeps its source URL, and deletion scoped to the source that owns the content.
Limits & next steps
Some sources are still maturing. Slack is a designed pattern and Jira MCP was an exploration. Neither is claimed here as a shipped connector.
Supported is not built alone. For SharePoint, my part was supporting onboarding and file-format compatibility.
No freshness metrics yet. The record has no figures for sync latency, stale-content rate or deletions applied. Next, I would report new, updated and deleted counts per sync, and the time from a source change to the index.
Validation counts are not usage. About 1,145 counts articles fetched in validation, not answers served.
Based on my documented work record, reviewed October 2026. Industry details are generalized: internal product names, repository and space names, credentials, employer code, private links and infrastructure identifiers are not reproduced. The counts are validation figures, not an independently audited benchmark.